
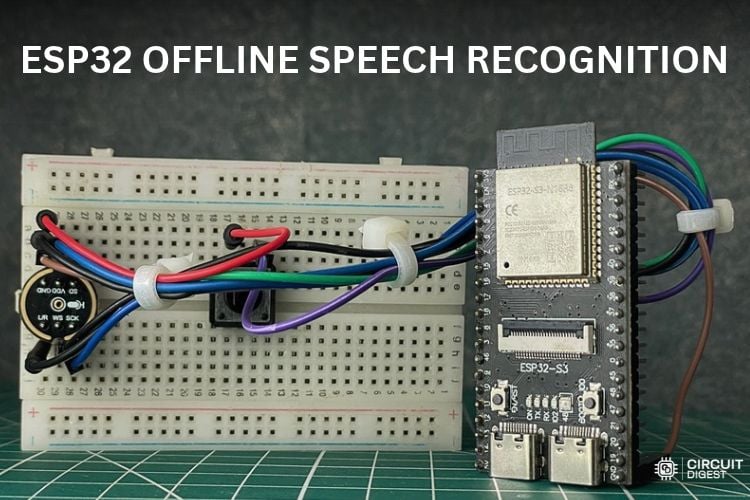
Speech recognition models like OpenAI’s Whisper offer high levels of accuracy, but their base model itself consumes up to 140MB and running them on a low-end device like an ESP32 is difficult. In this tutorial, we are going to run Cactus Compute’s Whisper Speech-to-Text Model launched on 2nd of October 2026. The actual size of the model is 16.9MB, which won't fit into an ESP32 with 16MB Flash. In this tutorial, we will compress the 16.9MB Cactus Whisper down to 14.52MB, so that it fits into the ESP32 Flash memory.
This setup reads audio via an INMP441 I²S digital microphone, processes speech upon a button press, and triggers live actions on an onboard RGB LED that's connected to the GPIO pin 48, all this 100% offline with zero cloud API dependencies. Several other cloud providers offer STT services as well. We have already covered one such tutorial using Wit.ai with minimal latency. If interested, you can check out our ESP32 Speech-to-Text using Wit tutorial as well. Now, let's check out the components required to build this project.
Components Required
Below are the components required to build this project.
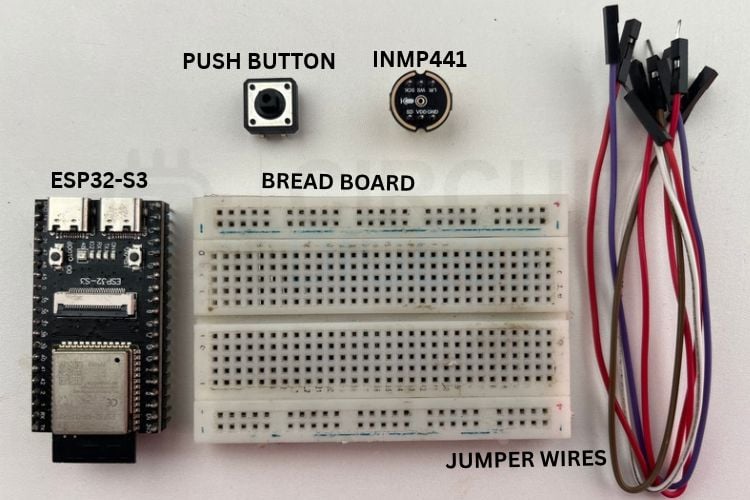
First, we have the ESP32-S3 board with 16MB of Flash and 8MB of PSRAM. This specific module is the ESP32-S3 CAM Module that comes with a camera. But we are not utilising the camera part in this project. Then we have the INMP441 microphone to record audio. The push button is used to trigger audio recording and stop it on press. We will be assembling the whole circuit on a breadboard, as it is the easiest way to get things started. Jumper wires will be used to make all the connections. Below is the list of components, neatly provided in a table for easy reference.
| S.no | Item | Description |
| 1 | ESP32-S3 | To be used as the main microcontroller |
| 2 | INMP441 I2S MIC | To record the audio |
| 3 | Push Button | To trigger audio recording and to stop recording |
| 4 | Breadboard | Where we will be setting up the circuit |
| 5 | Jumper Wires | To connect all the parts as per the circuit diagram |
Circuit Diagram
The following is the circuit diagram for this project.
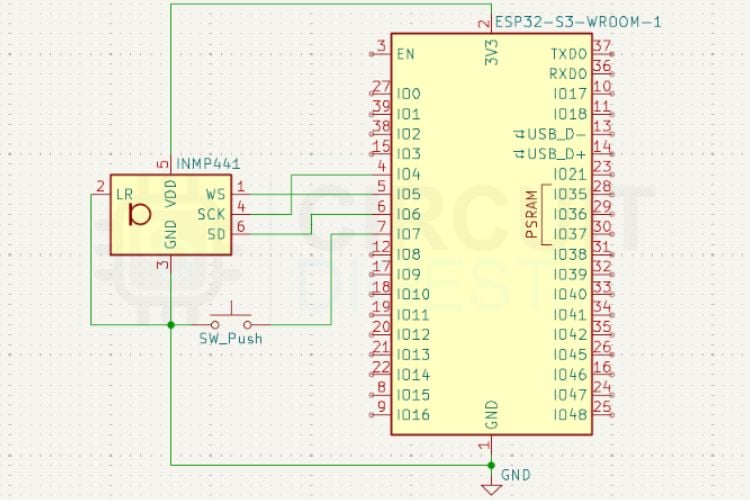
As in the circuit diagram, there are mainly 3 components. One is the ESP32-S3 Board itself, which has 16MB of Flash and 8MB of PSRAM, where we will be running the STT model. Then we have the INMP441 I2S microphone to capture the audio and then a push button pressing on which, it starts recording and releasing which it stops recording. We will be controlling the onboard RGB LED, which is connected to GPIO48 of the ESP32, using this setup, so we don’t need to connect any external output devices. But the code can be completely modified to meet the project requirements. Along with the onboard RGB LED response, we will have a response in the TUI(Terminal User Interface) Monitor as well.
Hardware Connections
Connect the INMP441 microphone and push button according to the following pinout. If you’re someone who wants offline speech recognition but doesn't want to use an ESP32 for that, we have a dedicated tutorial on Low-Cost Offline Voice Recognition using a low-cost module. Now, let's take a look at the connection required to set this up.
| Component Pin | ESP32-S3 Board Pin | Description |
| INMP441 VDD | 3V3 | Do NOT connect to 5V |
| INMP441 GND | GND | Ground |
| INMP441 L/R | GND | Selects left channel |
| INMP441 SCK | GPIO 4 | I²S bit clock |
| INMP441 WS | GPIO 5 | I²S word select |
| INMP441 SD | GPIO 6 | I²S serial data |
| Push Button Pin 1 | GPIO 7 | Uses internal pull-up |
| Push Button Pin 2 | GND | Ground |
| WS2812 RGB LED | GPIO 48 | Onboard LED (Default) |
Step-by-Step Instructions
We are going to use ESP-IDF. Download and install it from the official website. Here, in this tutorial, ESP-IDF Version 5.5.5 is being used. Version 5.5 or above is required. Once installed, open it from the Start menu and go to the desired directory where we plan to clone the repo. The following is the directory where we will be working. Let's CD into it.
cd $HOME\Documents\ProjectsClone the Whistle-ESP32 repository and CD into the project directory using the following commands.
git clone https://github.com/andrisgauracs/whistle-esp32.git
cd whistle-esp32
Let's create a virtual environment named “venv” so that we can install all the required packages in that venv.
python -m venv .venvActivate the newly created venv using the following command.
.\.venv\Scripts\Activate.ps1If it throws an error, run this command to unblock scripts for the current PowerShell session.
Set-ExecutionPolicy -ExecutionPolicy RemoteSigned -Scope ProcessInstall the required tools.
pip install numpy rich pyserial huggingface_hub
pip install esptool
Now, let's download & Strip the Whistle Model. Make sure we are in the following directory:
C:\Users\Pavilion\Documents\Projects\whistle-esp32
Create the model directory:
mkdir -Force model\whistleDownload the model from Hugging Face:
python -c "from huggingface_hub import hf_hub_download; import shutil; shutil.copy(hf_hub_download('Cactus-Compute/whistle','whistle.cact'), 'model/whistle/whistle.cact')"Strip the model down to 4 layers (14.5 MB):
python tools\whistle_strip.py model\whistle\whistle.cact 4 model\whistle\whistle_d4.cact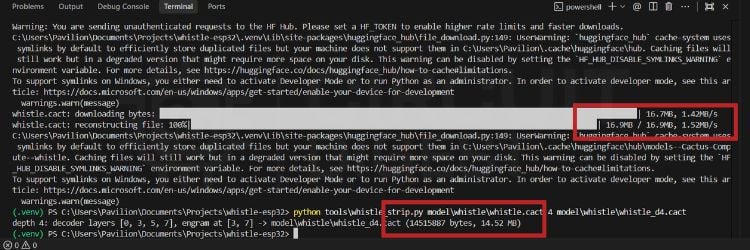
In the image above, we can clearly see the actual downloaded model size, which is 16.9MB and the size after stripping down the model, which is 14.52MB.
Make sure we are in the following directory :
C:\Users\Pavilion\Documents\Projects\whistle-esp32\esp32\whistle_demo
We don't want to activate the venv as of now, as the project's local virtual environment (.venv) may conflict with ESP-IDF's own dedicated Python environment. If it's activated by any chance, use the following command to deactivate it.
deactivateNow, the default installation directory for ESP-IDF 5.5 on Windows is usually inside the user directory or under C:\Espressif, rather than C:\esp-idf. We need to find that out.
Run this command in PowerShell to automatically find where export.ps1 is located on your machine:
Get-ChildItem -Path "C:\Espressif", "C:\Users\$env: USERNAME" -Filter "export.ps1" -Recurse -ErrorAction SilentlyContinue | Select-Object -ExpandProperty FullNameHow to Export ESP-IDF Based on the Location
Once the script outputs the path, run it with a dot operator at the beginning. For example:
If it is inside C:\Espressif:
. C:\Espressif\frameworks\esp-idf-v5.5.5\export.ps1Or if it is in your User directory:
. C:\Users\Pavilion\esp\esp-idf\export.ps1Build and Flash the Firmware
Now, let's proceed with the set-target and build commands:
idf.py set-target esp32s3
idf.py build
Flash the firmware using the following command. Replace the “x” with the actual COM Port of your ESP32. It can be seen in Device Manager on Windows.
idf.py -p COMx flashFlash the Model
Go back to the project rootcd ..\..
Reactivate the project venv.\.venv\Scripts\Activate.ps1
Flash the 14.52MB model binary to partition 0x210000esptool.py --chip esp32s3 -p COM6 -b 921600 write_flash 0x210000 model\whistle\whistle_d4.cact
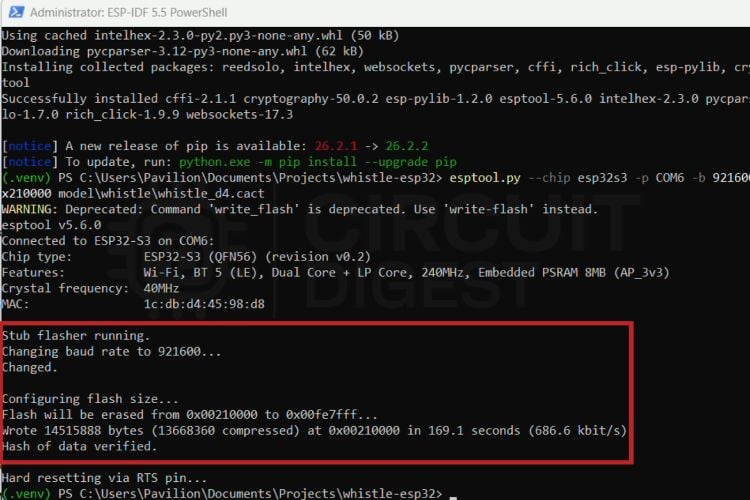
The above message will show up once the model is successfully flashed onto our ESP32.
Run the TUI(Terminal User Interface) Monitor
Once the model write reaches 100%, launch the TUI monitor to test your board.
At this point, we need to connect the ESP32-S3 board to its 2nd Type-C port labelled as USB-OTG instead of USB-UART. This is because the USB-UART port connects to the external CP2102 or CH340 USB-to-Serial bridge chip attached to the hardware UART0 pins (TX0/RX0).
Since the whistle-esp32 repository connects directly to the native USB peripheral inside the ESP32-S3 silicon, we need to connect it to the USB-OTG port.
Before running the following command, make sure to replace the “x” with the actual COM Port of the ESP32.
python tools\needle_tui.py --whistle --serial COMx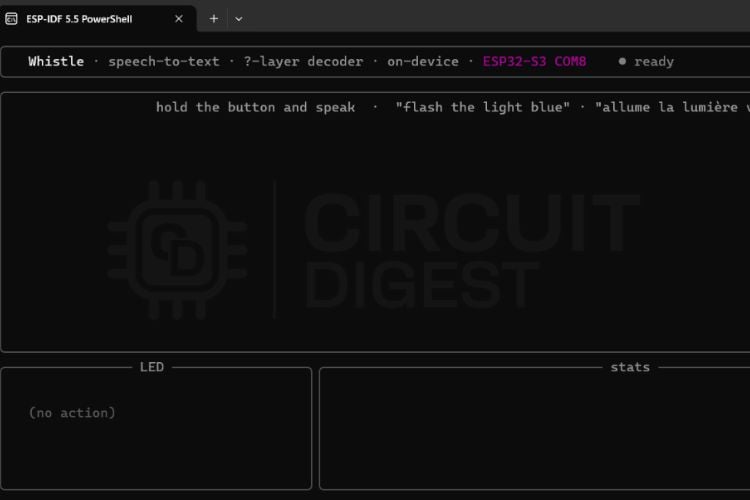
The above will be the TUI Monitor interface that will pop up immediately when we run the above command. It even shows ESP32-S3 is connected to COM8. Once we are at this level, we can proceed to the next steps and see the results.
Result
Below are some of the commands that can make some actions with this setup. Apart from the following set of commands, it can understand any context and perform some actions. As of now, we don't have too many I/O devices connected to it and programmed, so below are some valid commands. It even converts any random text that is spoken to it and displays it in the TUI Monitor.
| SNo | Command | Action |
| 1 | Change colour to Red | Red light flashes |
| 2 | Flash green light for 5 seconds | Green colour flashes for 5 seconds |
| 3 | Blink violet every half second | Violet blinks for half a second |
| 4 | Purple | Purple colour flashes |
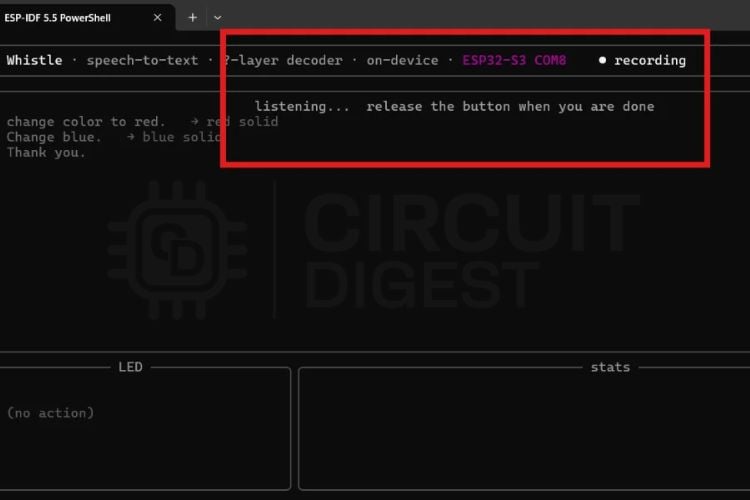
When the push button is pressed, the TUI Monitor shows the status as “Recording” and starts recording the audio that is spoken to the INMP441 Mic. The recording keeps going until the button is released. At this point, the onboard RGB LED shows white.
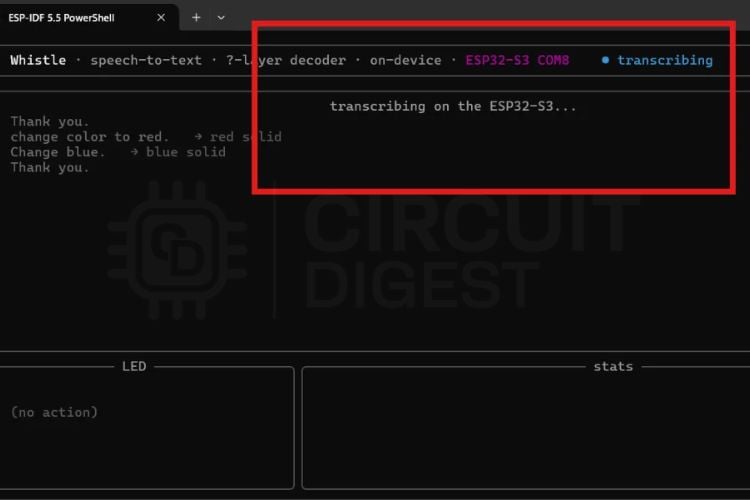
Once the button is released, the "Recording" status changes to “Transcribing”, meaning the spoken audio is being transcribed to text. This process typically takes 6 seconds. At this point, the onboard RGB LED blinks white slowly, indicating that transcription is going on. If no text is detected, it immediately blinks Red colour twice. The possible reason for this may be that the MIC is not good, or the MIC connection is wrong.
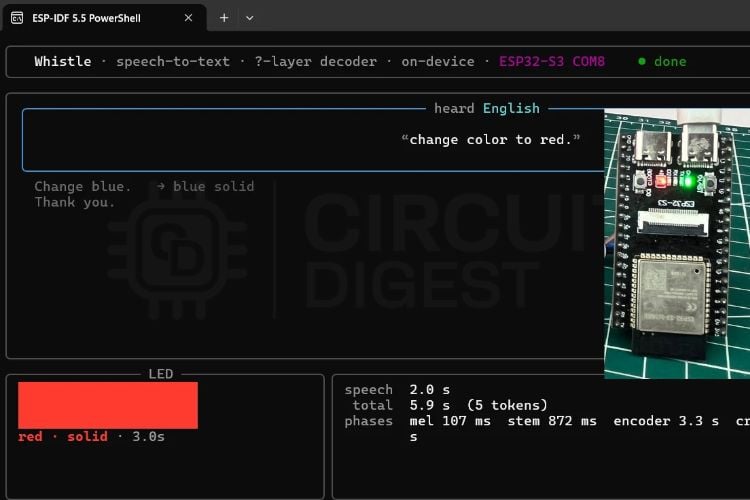
Once the transcription is done, we can see the output in the TUI Monitor. It displays the response to the action. For this command, the onboard RGB LED turns red. It behaves as per the command provided. It's also visible that this action took less than 6 seconds.
Run Voice Recognition locally on a $10 Chip- Demo
Conclusion
The successful deployment of Cactus Compute’s Whistle model on the ESP32-S3 demonstrates that modern, Transformer-based speech-to-text is no longer locked behind cloud APIs or high-power Linux single-board computers. By combining structural layer pruning with INT8 vector quantisation, a $10 microcontroller can run multilingual, offline speech recognition locally.
This project proves that privacy-first voice control, sub-second hardware response times, and zero-latency cloud independence are fully achievable on resource-constrained edge hardware. Now, if the transcribed text needs to be converted into audio, we have a dedicated tutorial that teaches how to build an ESP32 Text-to-Speech offline system so that this can also be integrated into this project. Text-to-speech can also be done using our ESP32-C3 Text-to-Speech Using Wit tutorial as well. For more ESP32-based projects, check out our collection of ESP32 projects.
Official Andrisgauracs GitHub Repository


Projects Related to Smart Offline Voice Assistant
This collection explores the development of smart, offline embedded systems using Arduino and ESP32 microcontrollers.It covers accessing Wikipedia without an internet connection, converting text into speech using Arduino, and implementing offline voice recognition using Edge Impulse. Together, these projects demonstrate how microcontrollers can enable intelligent, voice-controlled, and speech-based applications without relying on continuous internet connectivity.
DIY Raspberry Pi Pico Text-to-Speech Using Wit.ai
In Raspberry Pi Pico TTS setups, the Pico sends text to an online service where speech is generated and returned as audio. The device then plays the sound through a speaker, allowing clear speech output without overloading the hardware or increasing system complexity.
Arduino-based Text-to-Speech (TTS) Converter
In this tutorial, we will learn how to make a text-to-speech converter using Arduino. This step involves the conversion of the symbols, numbers and abbreviations into words that can be read by the machine.
ESP32 Offline Voice Recognition Using Edge Impulse
We’ll build a mini yet expandable ESP32 voice assistant using Edge Impulse, with the ESP32 as the main microcontroller. The goal of ESP32 offline speech recognition is to keep it simple while still leaving room for future upgrades.
Add a comment
No account needed. Your comment appears once a moderator has reviewed it.