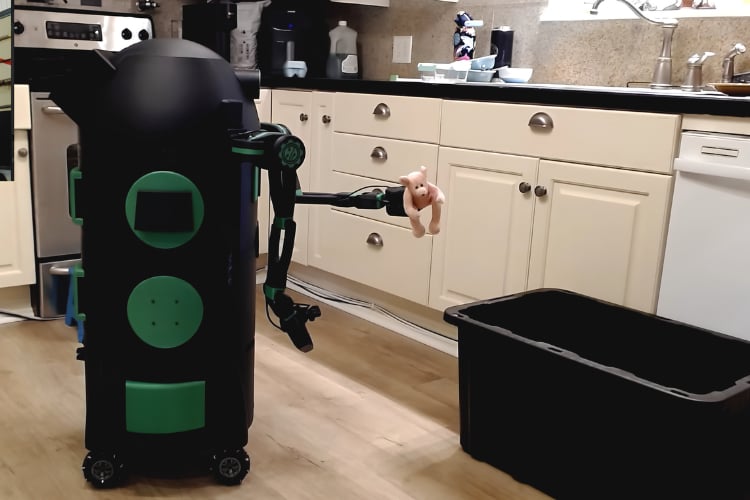
Harrison Kinsley, the YouTuber behind Sentdex, has shown a Vulcan Robotics Sourccey, a 3D-printed robot he calls “Chonk,” picking up a toy from the floor and dropping it in a bin with no task-specific training. In part three of his “Everything is LLM” series, published Oct 8, a general-purpose multimodal language model made the task decisions. The planning and control came from DeepSeek’s V4.1 Flash, which receives the robot’s camera images and knows its SDK. Kinsley says Z.ai’s GLM-5.3-Flash can also do the job. In his video, the demo is sped up 10x, and his fastest full run so far is about six minutes.
Rather than training a policy, Kinsley wrote a step-by-step prompt. The robot moves to a preset scouting pose, finds the object, lines it up with an approach corridor in the camera view, lowers the arm, and grips. It then checks whether it is still holding the object, locates the bin, and uses lidar to judge how close it is before depositing. The model is called about 90 times per task. Kinsley argues that latency matters little for a long-horizon chore like this, and says the vision-capable decision models he tried didn’t work well enough.
Calibration was the hardest part. Kinsley says the robot has five cameras plus a 2D lidar, set at different angles, and the gripper cameras move with the arm joints, so one motion shifts pixels differently in each view. He built a per-camera movement guide for the model, with GLM-5.3-Flash iterating in simulation before he tuned it on the real robot. While walking through the setup in the video, he says he spotted calibration problems he still needs to fix.
Add a comment
No account needed. Your comment appears once a moderator has reviewed it.