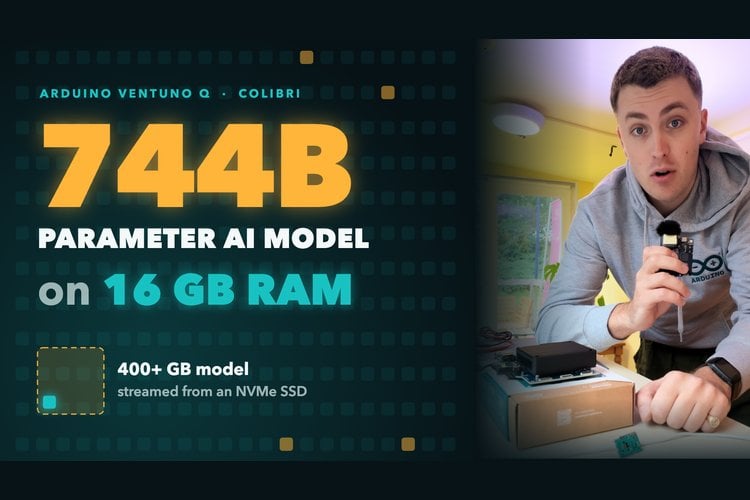
Large language models with hundreds of billions of parameters normally live in data centres, on servers with far more memory than any single-board computer. So it is a surprise to see one answer a question on an Arduino. In a project published on Arduino Project Hub, Jim Bruges ran GLM-5.3, a 744-billion-parameter model whose files take up about 419 GB, on an Arduino VENTUNO Q with just 16 GB of RAM. The trick is to stream the model from an NVMe SSD instead of loading it into memory. It works, but it is slow: asked to name three planets, the board answered "Earth, Mars, Venus" after about seven minutes.
How a 419 GB model runs on 16 GB of RAM
The project uses Colibri, an open-source inference engine (the software that actually runs a trained AI model and produces its answers) by JustVugg. Both models in the guide are mixture-of-experts models (models split into many smaller "expert" networks, where only a few experts are used for each token, so most of the model sits idle at any moment). Colibri takes advantage of that. It keeps a cache of experts in RAM and loads the others from the SSD only when they are needed. As the guide puts it, the SSD is part of the inference system, not just a place to keep the files.
The VENTUNO Q is Arduino's most powerful board so far. It pairs a Qualcomm Dragonwing IQ8 (QCS8275) processor running Ubuntu Linux with an STM32H5 microcontroller for real-time control, and it has 16 GB of LPDDR5 RAM and an M.2 slot for an NVMe Gen 4 SSD. This project uses only the Linux side, with a 1 TB Crucial NVMe SSD. There is no sketch and no wiring. The guide shows how to mount the SSD, build Colibri's CPU engines and browser dashboard with Docker, download the models and talk to them through a web page or a short Python script.
Key details
- Board: Arduino VENTUNO Q, 16 GB RAM, Ubuntu 24.04, models on a 1 TB NVMe SSD
- Models: Qwen3.6-35B-A3B (about 23.1 GB) and GLM-5.3 744B (about 419.3 GB, 148 files)
- Qwen speed: about 0.74 tokens per second with 96 cache slots per layer, about 0.77 with performance CPU governors, about 35 s to the first token
- GLM speed: about 0.030 tokens per second. The planet prompt took 252 s to process and 167 s to produce five tokens, about 7 minutes in total
- CPU use: four threads on the Cortex-A78C performance cores beat both two threads and all eight cores
- GPU and NPU: an early Vulkan GPU test was slower than the CPU, and the NPU is not used, because Colibri has no Qualcomm backend yet
- Licence: project MPL-2.0
Our take
The honest numbers are what make this guide worth reading. Bruges says plainly that "working does not mean fast". The 744B model is an experiment in expert streaming, not something you would chat with, and a bigger parameter count does not guarantee better answers on your task. The smaller Qwen model is the practical one, and the guide suggests uses like short log classification, small code suggestions or a local maintenance assistant where waiting half a minute is fine.
There are two useful lessons for anyone planning edge AI. First, for mixture-of-experts models, storage speed and cache size matter as much as raw compute: going from 32 to 96 cache slots made Qwen about 48 percent faster, while CPU governor tuning added only about 5 percent. Second, the board's 40 TOPS NPU sat idle here, so the real speed-up will come when an engine can actually use it. The full guide, with the launcher script and every command, is on Arduino Project Hub, and the engine is on GitHub.
Image credit: Jim Bruges, Arduino Project Hub cover image, resized.
About the author: Aswinth Raj is an electronics engineer and the editor of CircuitDigest, where he has published more than 150 hands-on projects and tutorials across Arduino, PIC, ESP32, Raspberry Pi and EV battery systems. He selects the stories on this page for what engineers and makers can actually learn or build from. Connect on LinkedIn
Add a comment
No account needed. Your comment appears once a moderator has reviewed it.